AI models
AI image, video and voice models, tested
One page per model: what it costs, what the free tier really gives you, which settings matter and what they look like, and the same prompts run through every model so you can compare real output. Twelve pictures for every image model, nine clips for every video model, four scripts for every voice model. Each picture below is the model drawing itself.
Compared
The same prompts across every model, ranked with a verdict, and the pairs people ask about.
The best AI image generator, tested
Twelve prompts through 36 AI image models, from Nano Banana, GPT Image and FLUX to Krea, Meta and Microsoft, every picture kept. Prices, speed and a verdict per prompt.
The best AI video generator, tested
The same nine prompts through 30 AI video models, Veo, Kling, Seedance, FLUX, Sora, Wan, Hailuo, MiniMax and more, every clip kept. Prices, waits and a verdict per prompt.
One prompt, every image model
Text in an image
Which AI image model renders text best
Product on white
Which AI image model makes the best product shot on white
Face and hands
Which AI image model does faces and hands best
Logo mark
Which AI image model makes the best logo
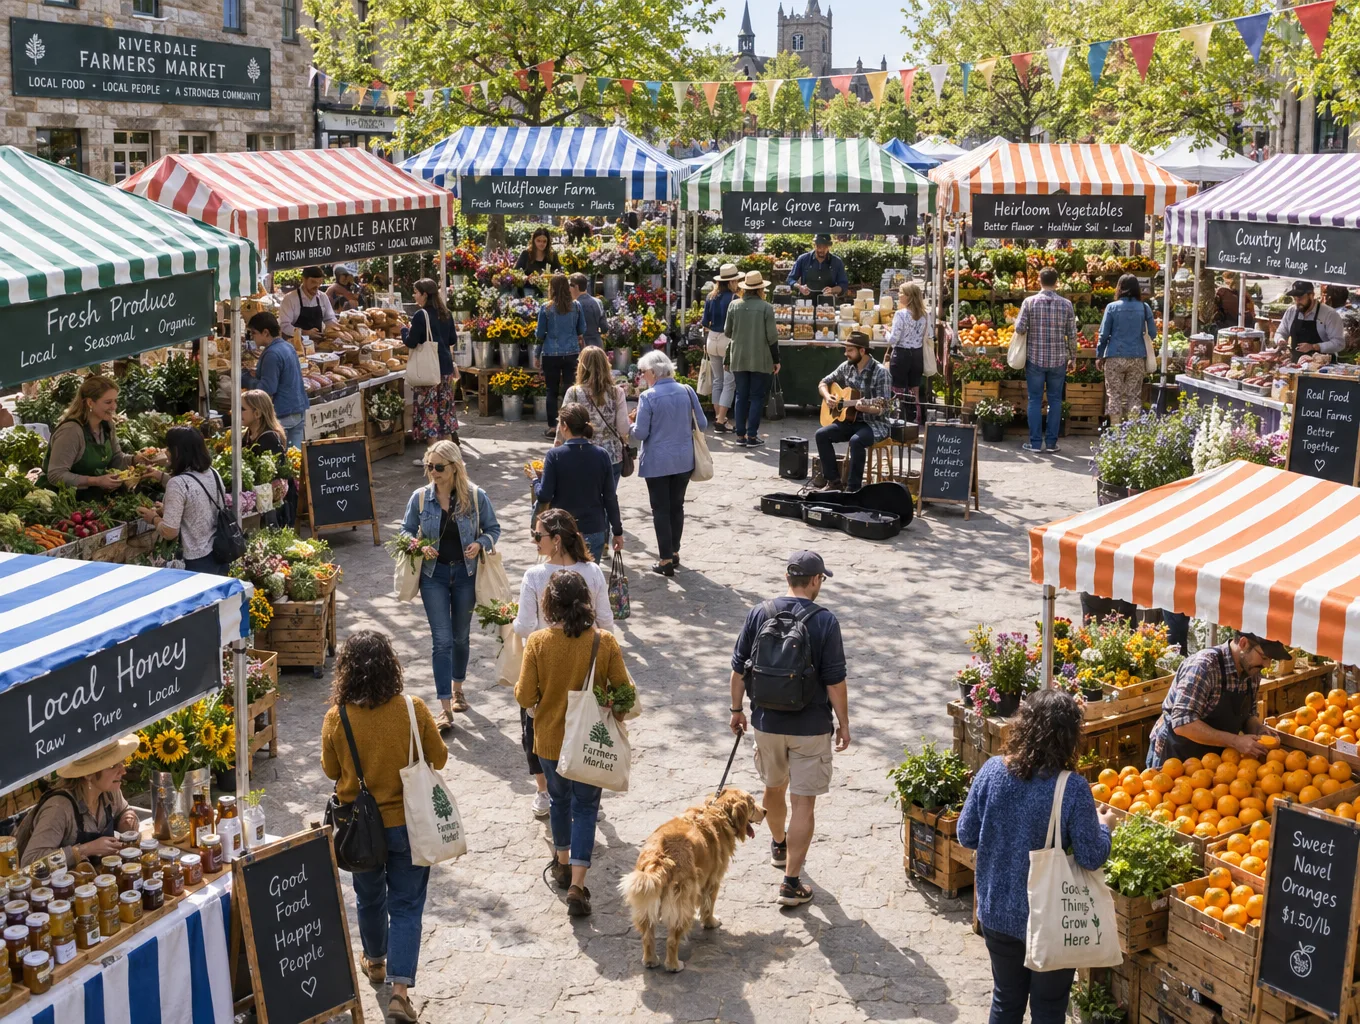
Busy scene
Which AI image model handles a busy scene best
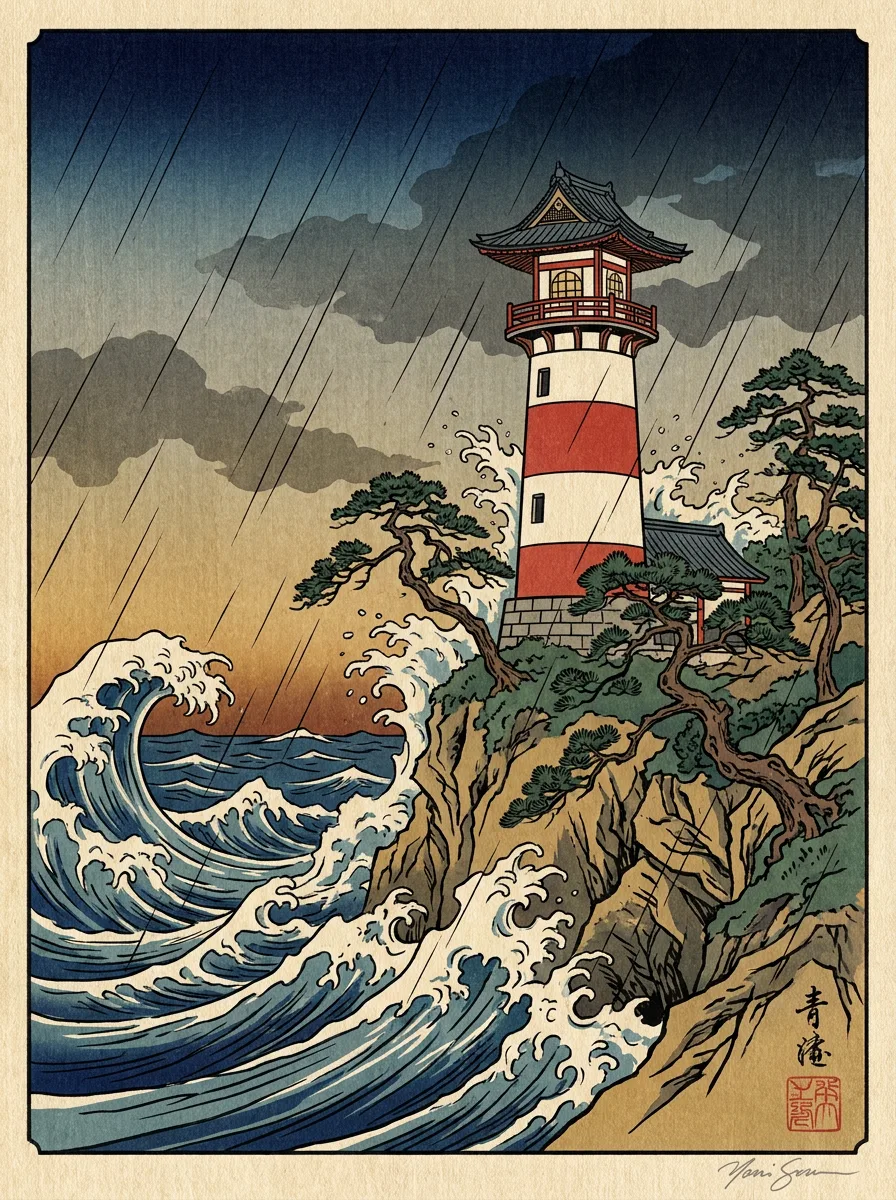
Specific art style
Which AI image model holds an art style
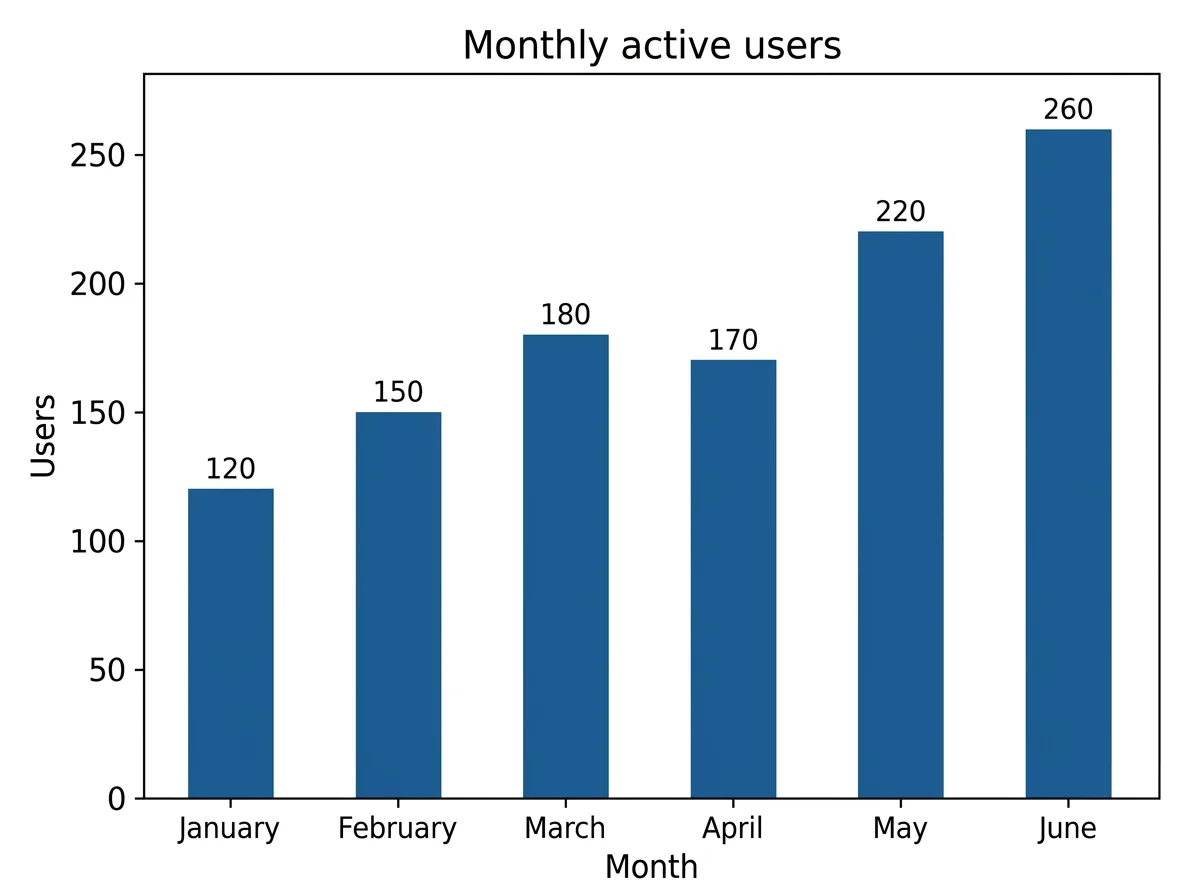
Chart
Which AI image model draws an accurate chart
Wide aspect ratio
Which AI image model makes the best wide banner
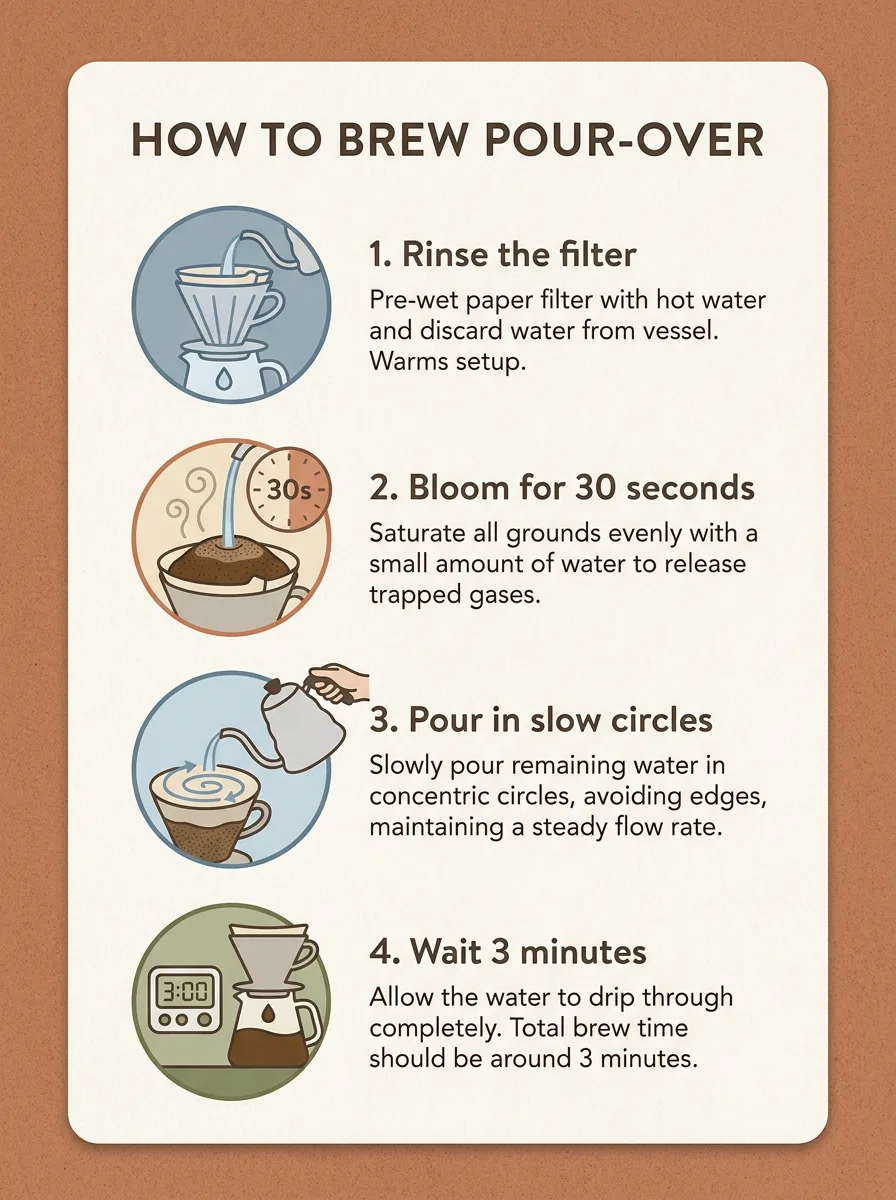
Infographic with steps
Which AI image model makes the best infographic
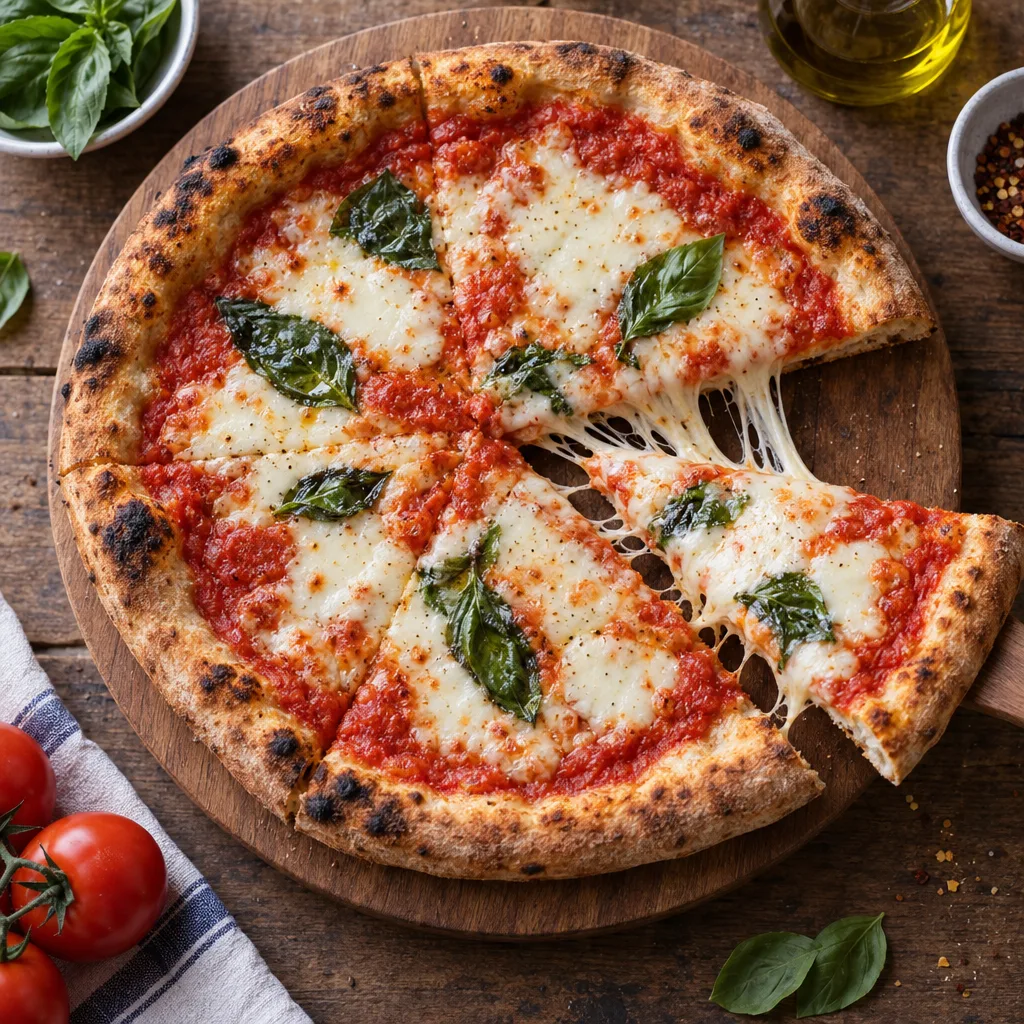
Food photography
Which AI image model makes the best food photo
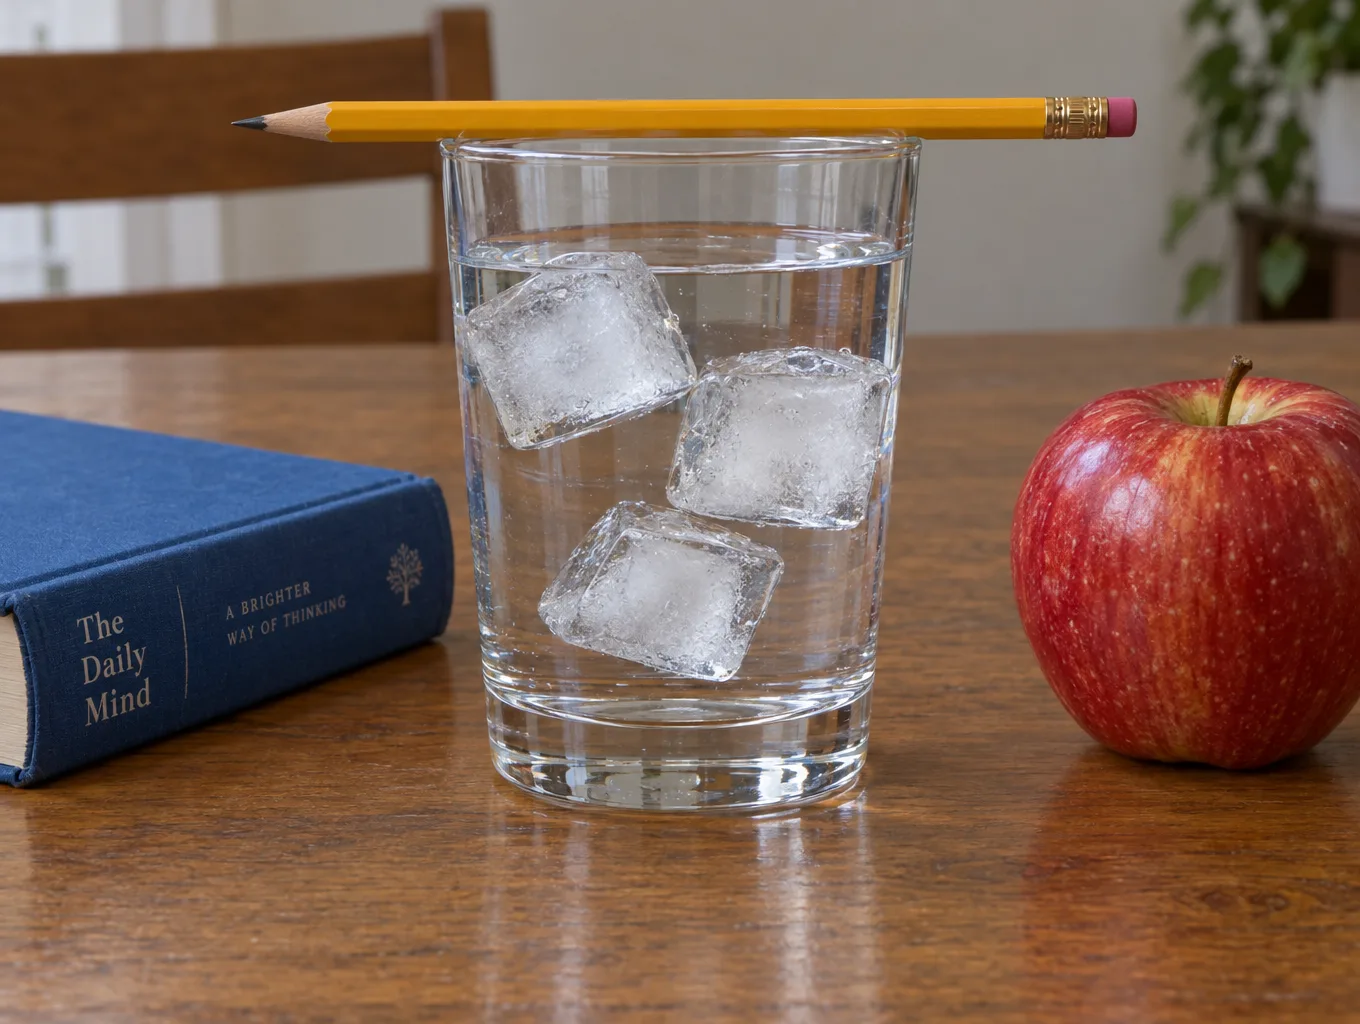
Hard composition
Which AI image model follows a hard composition
Edit an existing image
Which AI image model edits a picture best
One prompt, every video model
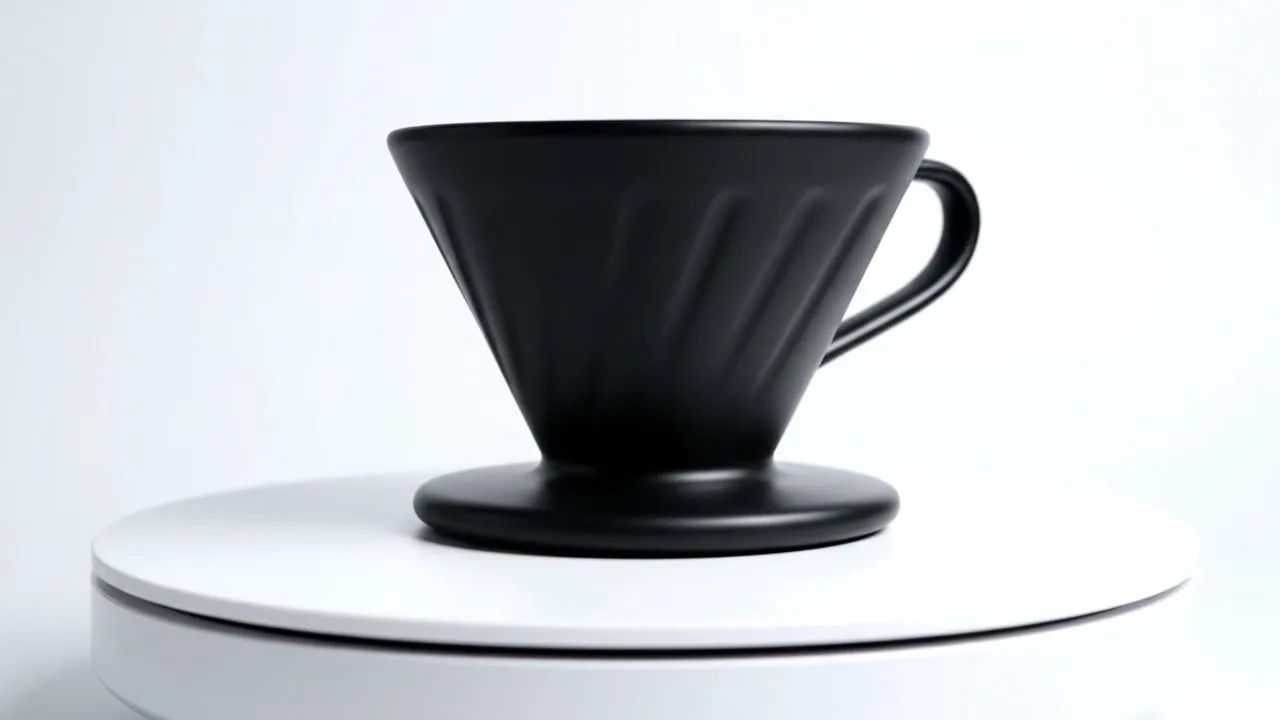
Product turntable
Which AI video model makes the best product turntable
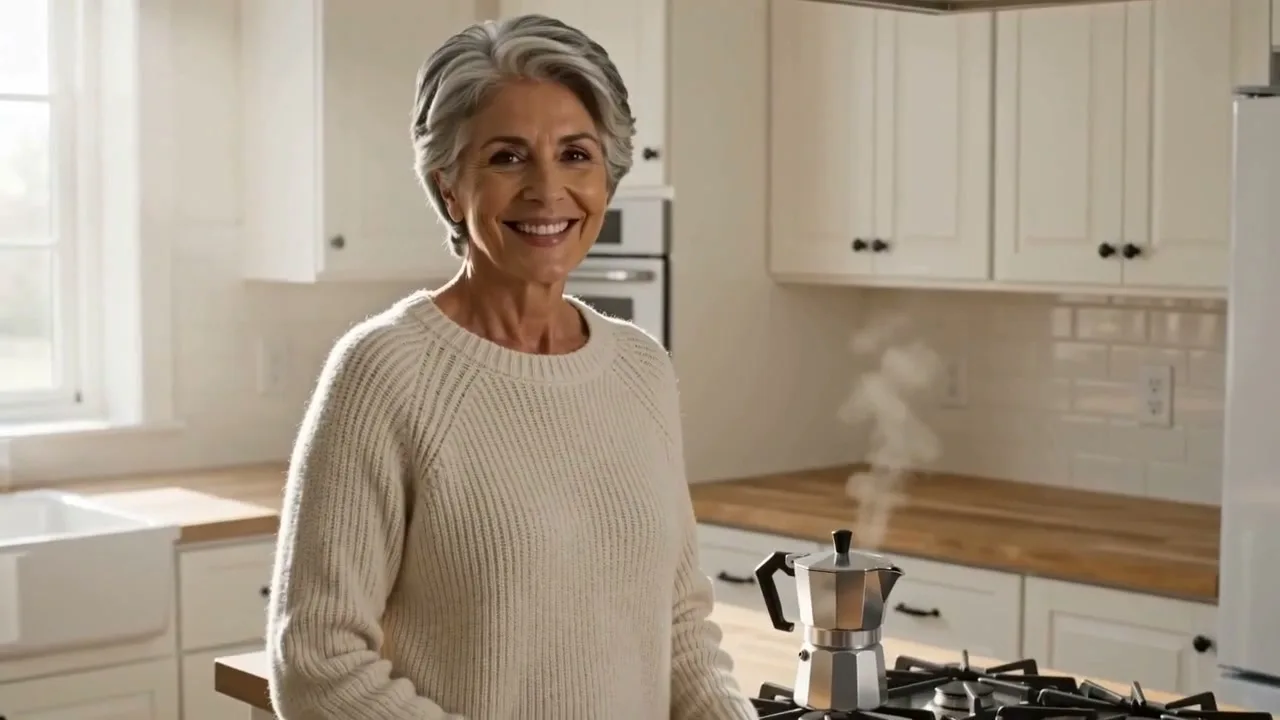
Person speaking
Which AI video model makes the best talking head
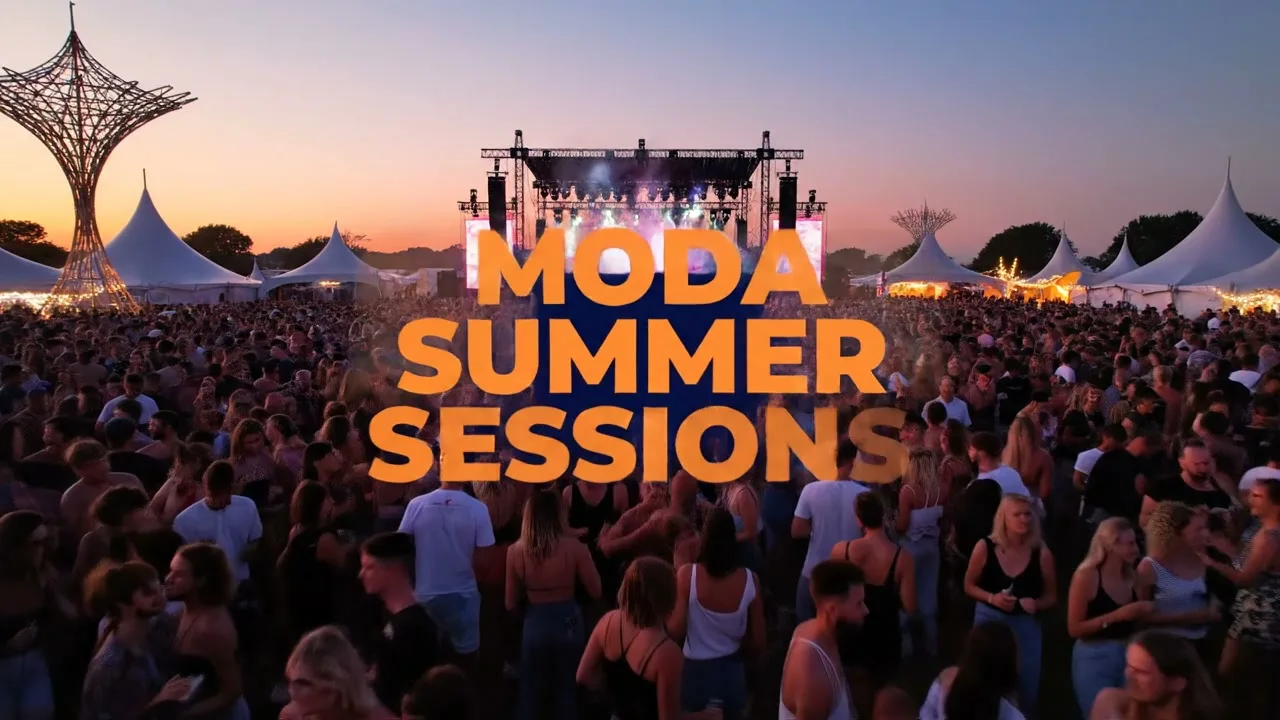
Animated title card
Which AI video model can render text on screen
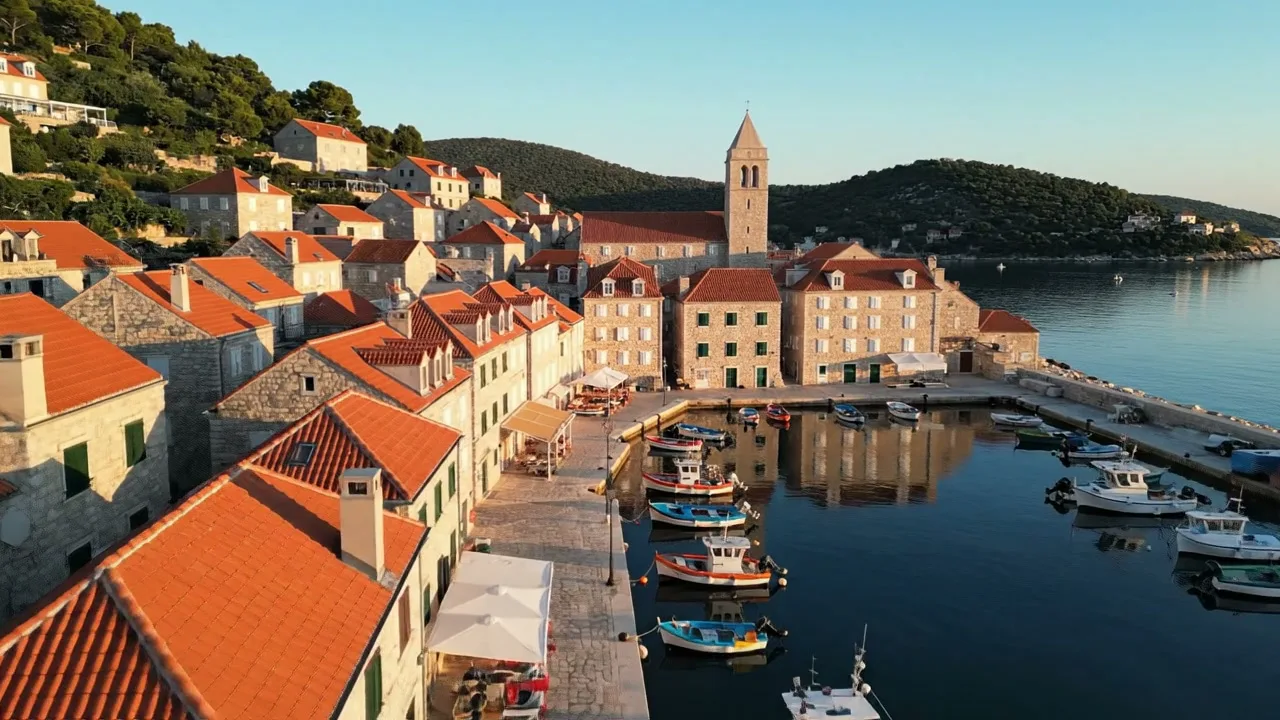
Camera move
Which AI video model handles a camera move best
Physics
Which AI video model gets physics right
Hands at work
Which AI video model handles hands and objects best
Busy scene
Which AI video model handles a busy scene best
Specific art style
Which AI video model holds an art style
Image to video
Which AI image-to-video model keeps the product intact
Head to head
Image models
Every image model that works from a prompt runs the same 12 prompts; editing models run a fixed set of edits.
Bria
Black Forest Labs
FLUX 3 Image
$0.048 per 1k image, about 1 megapixel via BFL API
Black Forest Labs' October 2026 image model: native 2K and 4K, up to 10 references, one flat price per image by size.
FLUX 3 Image Klein
$0.009 per 1k image via fal
Black Forest Labs' small open-weights FLUX 3: about a cent a 1K image on fal, three seconds a picture, and a clean, one-pass product edit.
FLUX.2 Pro
$0.03 per 1k image via BFL API
Black Forest Labs' production model: 3 cents a megapixel, photoreal, no knobs to tune.
FLUX.2 Flex
$0.05 per 1k image via BFL API
The FLUX.2 tier with knobs: steps and guidance you can tune, better typography, 5 cents a megapixel.
FLUX.2 Max
$0.07 per 1k image via BFL API
The top FLUX.2 tier: 7 cents a megapixel for BFL's most realistic and precise output and edits.
OpenAI
GPT Image 2.6 Flare
$0.053 per 1024 by 1024, high quality via API list price
Clean text, transparency, careful edits and quick GIFs.
GPT Image 2.6 Sunburst
$0.053 per 1024 by 1024, high quality via API list price
Intricate hero art, showcase GIFs and demanding revisions, slower.
GPT Image 2.5 Flare
$0.053 per 1024 by 1024, high quality via fal
OpenAI's fast default since September 2026: GPT Image 2's tricks, faster, and a quarter of the price at high quality.
GPT Image 2.5 Sunburst
$0.053 per 1024 by 1024, high quality via fal
OpenAI's precision tier: same prices as Flare, slower, built for edits where fidelity to the original matters most.
GPT Image 2
$0.21 per 1024 by 1024, high quality via fal
The model behind ChatGPT's image generator from April to September 2026: exact sizes, cut-outs, precise edits, slow at high quality.
xAI
HiDream.ai
Ideogram
Ideogram 4.5
$0.06 per image, medium quality via fal
Ideogram's edit-first update: a flat price per image at any size, text that held at every quality tier, and edits that leave the rest of the picture alone.
Ideogram 4.5 Precise Edit
$0.06 per edit, medium quality via Ideogram API
Ideogram's region editor: change one area of a photo up to 8192 by 8192 at its original pixels, from $0.008 an image, and get the rest back as sent.
Ideogram 4.0
$0.015 per 1024 by 1024, balanced via fal
Ideogram's first open-weight model: built for design and type, three rendering speeds from under a cent a megapixel.
Ideogram Vector
$0.16 per generated svg, medium quality via fal
Generate editable SVG graphics from a prompt, or convert an existing image to SVG with default and simple modes.
Krea
Krea 3
$0.025 per megapixel of output, plus each reference via fal
Krea's October 2026 model: native 2K, the most photographic results in this batch, a clean edit, and much slower through fal than Krea advertises.
Krea 2 Medium
$0.03 per image without style references via fal
Krea 2 Medium is the smaller hosted Krea 2 image model.
Krea 2 Large
$0.06 per image without style references via fal
Krea 2 Large is the higher-priced hosted Krea 2 image model.
Microsoft
MAI-Image-2.5
$0.05 per image via fal
Microsoft's own image model: about five cents an image on fal, strong photographs and scenes, small output and shaky small type.
MAI-Image-2.5 Pro
$0.17 per image, average text-to-image request via fal
Microsoft's quality tier: cleaner type and a real handle on the edit, at about 17 cents for an image of one megapixel or less.
Meta
OpenMOSS
Google DeepMind
Nano Banana 2.1
$0.034 per 1k image via Gemini API
Google's October update to Nano Banana 2: thinking on by default, no 512px size, and about half the API price per 1K image.
Nano Banana 2
$0.067 per 1k image via Gemini API
Google's everyday model and the Gemini app default: near-Pro quality at Flash speed and half the price.
Nano Banana 2 Lite
$0.034 per 1k image via Gemini API
The cheapest and fastest Nano Banana: about $0.034 an image and a few seconds each, at a fixed 1K.
Nano Banana Pro
$0.13 per 1k or 2k image via Gemini API
Google's premium tier: the best at text and complex briefs, the slowest and dearest of the three.
Alibaba
Recraft
Recraft V4.1
$0.035 per raster image via Recraft API
Recraft's design-first model: brand colours as an input, real SVG in the vector variant, 3.5 cents an image.
Recraft V4.1 Flash
$0.007 per image via fal
Recraft's cheapest model: 0.7 cents a raster image on fal, a designer's eye for posters, and no styles, vector output or editing.
Recraft V3
$0.04 per raster image via Recraft API
Recraft's 2024 model, still on sale: 70 named styles, an image-to-image endpoint, 4 cents an image.
ByteDance
Seedream 5.0 Pro
$0.068 per image up to 1536 by 1536 in area via fal
ByteDance's flagship: reasons before it draws, text in 14 languages, dense layouts, under 7 cents at 1K.
Seedream 5.0 Lite
$0.035 per image via fal
ByteDance's fast tier: 3.5 cents an image, 2K to 4K output, up to ten reference images.
Seedream 5.0 Flash
$0.027 per image via fal
ByteDance's cheapest Seedream 5.0 tier: 2.7 cents an image on fal at 1K or 2K, about 15 seconds a picture, with an edit endpoint.
Seedream 4.5
$0.04 per image via fal
ByteDance's late-2025 model: 4 cents an image, 2K and 4K, generation and editing in one model.
Video models
Every video model that works from a prompt runs the same 9 clips, five seconds each where the model allows it; editing models run a fixed set of clip edits.
Black Forest Labs
Google DeepMind
Gemini Omni Flash 1.1
$0.10 per second at 720p via fal
Google's Omni Flash video model, version 1.1 on fal: 3 to 10 second clips with sound, from 360p drafts to 4K, $0.10 a second at 720p.
Gemini Omni Flash
$0.10 per second of 720p video via Gemini API
Google's conversational video model: 720p clips of 3 to 10 seconds with sound, edited by talking, $0.13 a second on fal.
xAI
Grok Imagine Video 1.5
$0.08 per second via xAI API
xAI's video model: 5 to 8 second clips with dialogue and effects, seven shapes, $0.14 a second at 720p, quick.
Grok Imagine Video 1.5 Lite
$0.03 per second at 720p via fal
xAI's low-cost tier of Grok Imagine Video 1.5: 1 to 15 second clips with sound at $0.03 a second at 720p on fal.
MiniMax
HeyGen Video
$0.02 per second at 768p via fal
MiniMax H3 post-trained by HeyGen: 5 to 15 second clips with sound, $0.02 a second at 768p, the lowest price on our roster.
H3 Max Turbo
$0.04 per second at 768p via fal
H3 Max Turbo is fal’s lower-priced post-trained MiniMax H3 variant.
H3 Max
$0.08 per second at 768p via fal
fal post-trains MiniMax H3 for prompt adherence and faster video generation.
MiniMax H3
$0.06 per second at 768p via fal
MiniMax's July 2026 omni-modal model: native stereo sound, up to 2K and 15 seconds, open weights, from $0.05 a second.
Hailuo 2.3
$0.28 per six-second clip, standard 768p via fal
MiniMax's October 2025 model at a flat price: $0.28 for six seconds at 768p, no audio, no settings to learn.
Alibaba
Kandinsky Lab
Kandinsky 6.0 Pro
$1.35 per five-second 480p clip, text-to-video via fal
Kandinsky Lab's flagship open-weight video model: five-second 480p clips with sound, MIT licensed, $1.35 a clip on fal.
Kandinsky 6.0 Lite
$0.16 per five-second 480p clip, text-to-video via fal
Kandinsky Lab's small open-weight video model: five-second 480p clips with sound, MIT licensed, $0.16 a clip on fal.
Kuaishou
Kling 4.0
$0.16 per second at 720p via fal
Kuaishou's October model: up to 30 seconds with stereo sound, per-shot prompts and up to 15 references, from $0.157 a second at 720p.
Kling 3.0 Standard
$0.13 per second, audio on via fal
Kuaishou's everyday tier: 15-second clips with audio, multi-shot storyboards, $0.126 a second with sound on fal.
Kling 3.0 Pro
$0.17 per second, audio on via fal
Kuaishou's higher-fidelity tier: the same 15-second, multi-shot envelope as Standard at $0.168 a second with audio.
Lightricks
LTX 2.5 Pro
$0.12 per second at 720p via fal
Lightricks' quality tier of LTX 2.5, the open-weight audio and video model: 6 to 10 second clips with sound at $0.12 a second at 720p on fal.
LTX 2.5 Fast
$0.09 per second at 720p via fal
Lightricks' speed tier of LTX 2.5: 6 to 20 second clips with sound, up to 4K, $0.09 a second at 720p on fal.
LTX 2.3
$0.08 per second at 1080p via fal
LTX 2.3 is Lightricks’ video model.
Luma AI
PixVerse
ByteDance
Seedance 2.0
$0.30 per second at 720p, 16:9 via fal
ByteDance's February 2026 model: native audio, up to 15 seconds and 4K, about $1.50 for five seconds at 720p.
Seedance 2.5
$0.46 per second at 720p, 16:9 via fal
ByteDance's July 2026 model: one continuous shot up to 30 seconds, 50 references, about $2.30 for five seconds at 720p.
Seedance 2.0 Mini
$0.007 per 1,000 tokens via fal
ByteDance's low-cost tier of Seedance 2.0: 4 to 15 second clips with sound at 480p or 720p, half the token price of the full model.
OpenAI
Google DeepMind
Veo 3.1 Fast
$0.15 per second with audio, 720p or 1080p via fal
Google's speed tier and the sensible default: the same audio, shapes and lengths as Veo 3.1 at $0.15 a second with sound.
Veo 3.1
$0.40 per second with audio, 720p or 1080p via fal
Google's flagship: native audio, reference images, 4K, and the dearest per second here at $0.40 with sound.
Veo 3.1 Lite
$0.05 per second with audio, 720p via fal
Google's budget tier from March 2026: 720p and 1080p only, $0.05 a second with audio.
Alibaba
Wan 3.0
$0.10 per second at 720p via fal
Alibaba's August 2026 model: 2 to 30 seconds in one pass with audio, $0.10 a second at 720p, hosted only.
Wan 3.0 Prime
$0.14 per second at 720p via fal
The fast tier of Alibaba's Wan 3.0: 2 to 30 second clips with sound, $0.14 a second at 720p on fal.
Wan 2.7
$0.10 per second at 720p via fal
Alibaba's April 2026 model: 2 to 15 seconds with native audio and a thinking mode, $0.10 a second at 720p, hosted only.
Voice models
Every voice model reads the same 4 scripts, plain text with no vendor tags.
ElevenLabs
Eleven v4
$0.08 per 1,000 characters via fal
ElevenLabs' expressive model from 28 September 2026: audio tags, more than 90 languages, $0.08 per thousand characters, a fifth less than v3 was.
Eleven v4 Turbo
$0.04 per 1,000 characters via fal
The low-latency sibling of Eleven v4, released the same day for voice agents: more than 90 languages, $0.04 per thousand characters.
Eleven v3
$0.10 per 1,000 characters via fal
ElevenLabs' expressive model, in general release since March 2026: audio tags for emotion, 70-plus languages, $0.10 per thousand characters on fal.
Google DeepMind
Gemini 3.8 Flash TTS
$0.045 per 1,000 characters via fal
Google's flagship voice model from 23 September 2026: style directions, two-speaker dialogue, 30 voices on fal, $0.045 per thousand characters.
Gemini 3.8 Flash Lite TTS
$0.03 per 1,000 characters via fal
The cheaper tier of Google's Gemini 3.8 voice models, for dubbing and voice agents: the same controls as Flash, $0.03 per thousand characters on fal.
Gemini 3.1 Flash TTS
$0.05 per 1,000 characters via fal
Google's voice model: 30 voices, style directions in plain language, multi-speaker scripts, 80-plus languages, $0.05 per thousand characters on fal.
HeyGen
HeyGen Voice
$0.03 per 1,000 characters via fal
HeyGen's own text-to-speech model from 9 October 2026: 24 library voices on fal, cloning from a recording, 39 languages, $0.03 per thousand characters.
HeyGen Voice Turbo
$0.004 per 1,000 characters via fal
The fast, low-cost tier of HeyGen Voice: the same voices, cloning and languages, $0.004 per thousand characters on fal, the cheapest voice on this site.
hexgrad
MiniMax
Every image model page runs the same 12 prompts (prompt set 2026-09-09): text in an image, a product on white, a face and hands, a logo, a busy scene, a named art style, a chart, a wide banner, an infographic, food, a hard composition and an edit of an earlier result. Every video model page runs the same 9 clips (clip set 2026-09-09): a product turntable, a person speaking, a title card, a camera move, a spill, hands at work, a busy scene, a named art style and a clip started from one of the image results. Output is shown as it came back.